When I started learning statistics, I expected formulas on the first page. Instead, I found a question I could not answer:
How can we know what 20,000 people think by asking only 500 of them?
Honestly, it felt like cheating. How can a small group speak for a big group?
This diary entry is about how I stopped thinking it was cheating, and started thinking it was actually brilliant.
Let me explain with a very small question.
A small question: coffee or tea?
Imagine I want to know: do people in my office prefer coffee or tea?
There are 200 people in the building. The easiest way is to ask all of them. But in real life, that is hard. Some people are busy, some are travelling, and some never reply to messages (we all know someone like this).
So I do something easier. I ask the 12 people who sit on my floor.
This small decision is where statistics begins. Almost every statistics problem looks like this:
We want to understand a big group, but we can only look at a small part of it.
Factories do this when they test a few samples instead of all 100,000. Companies do this when they test a new product with some customers before selling it everywhere. Election polls do this too.
And this brings us to the first two important words.
Who do we actually care about? – “Population”
The population is the whole group we want to understand.
In my coffee example, the population is all 200 people in the office.
This part confused me at first. I thought “population” meant the people living in a country. But in statistics, it simply means the whole group you care about. It can be people, but it can also be products, bank transactions, or rainy days.
The people we actually ask – “Sample”
The sample is the smaller group that we actually collect data from.
In my example, the sample is the 12 people on my floor.
A short way to remember:
Population = the whole group we want to understand.
Sample = the small group we actually study.
🔍 For the curious: A number that describes the population (for example, the true share of coffee lovers in the whole office) is called a parameter. We usually cannot see it directly. A number calculated from the sample (for example, 7 out of 12) is called a statistic. A big part of statistics is using the statistic to estimate the parameter, and saying how sure we are.
My results
Here is what my 12 colleagues told me:
| Drink | Coffee | Tea | Neither |
|---|---|---|---|
| Number of people | 7 | 3 | 2 |
With this small table, I can do two different things. And these two things are the two main parts of statistics.
“Here is what I saw” – Descriptive statistics
Descriptive statistics describes the data we already have.
From my table, I can say:
“Among the 12 people I asked, 7 prefer coffee.”
That’s all. I am not guessing anything. I am only reporting what happened in my sample.
Averages, the highest and lowest values, the most common answer, and charts are all tools of descriptive statistics. They answer one question: What does my data look like?
“Here is what I think is true for everyone” – Inferential statistics
Inferential statistics goes one step further. It uses the sample to say something about the whole population.
“Based on my sample, most people in the office probably prefer coffee.”
Now I am making a guess about 200 people using answers from only 12. That is called an inference.
This was my “aha” moment:
- Descriptive = what happened in my data.
- Inferential = what I think happened in the whole group.
Notice the word “probably“. Because we did not ask everyone, there is always some uncertainty. At first, I thought uncertainty was a weakness. Now I think the opposite: statistics is one of the few subjects that tells you honestly how unsure you should be.
🔍 For the curious: Even a perfectly random sample will not match the population exactly. This natural difference is called sampling error, and it usually becomes smaller when the sample becomes bigger. Later in this series, we will meet tools such as confidence intervals that measure it.
The drama: when your sample lies to you
Here is the problem I did not notice at first.
The 12 people on my floor all work in the same team. And our team has a coffee machine right next to our desks. Of course we like coffee!
So, is my sample a fair picture of the whole office? Probably not. People on other floors might love tea, and I never asked them.
When a sample is not a fair picture of the population, we say it is biased. A biased sample can give a wrong answer, even when every calculation is correct.
And here is the surprising part: asking more people does not fix this. If I asked 50 people, but all from my floor, my answer would still be wrong. It would just be wrong with more confidence.
🔍 For the curious: A famous example is the 1936 US presidential election. The magazine Literary Digest collected about 2.4 million answers and predicted that Alf Landon would win. In the end, Franklin D. Roosevelt won by a very large margin. The magazine’s mailing list came mostly from phone books, car registrations, and its own readers, and in 1936 these people were richer than the average voter. (Many researchers also point out that the people who chose to reply were different from those who did not.) Meanwhile, George Gallup used a much smaller but better-chosen sample and predicted the right winner. The lesson: a good sample beats a big sample.
So the real question behind every sample is:
Does my sample fairly represent the population?
We will come back to this question many times in this series.
Two kinds of data
Before we analyze data, it helps to know what kind of data we have. There are two basic types.
Qualitative data is made of categories or labels. It tells us what type something is.
- My coffee question is qualitative: “coffee”, “tea”, and “neither” are categories.
- Other examples: favorite color, type of phone, payment method, country of birth.
Quantitative data is made of numbers that measure how much or how many.
- If I asked “How many cups do you drink per day?”, the answers (0, 1, 2, 3…) would be quantitative.
- Other examples: age, height, salary, waiting time.
An easy way to remember:
Qualitative → quality → what kind?
Quantitative → quantity → how much?
Why does this matter? Because different types of data need different methods. I can calculate the average number of cups per day. But I cannot calculate the “average drink” between coffee and tea. It doesn’t make sense.
🔍 For the curious: Each type can be divided further. Qualitative data can be nominal (no natural order, like coffee and tea) or ordinal (with an order, like “dislike, neutral, like”). Quantitative data can be discrete (counts, like cups per day) or continuous (measurements, like height). These details decide which charts and tests make sense.
The thing nobody told me at the start
When I started studying statistics more seriously, I learned something that changed how I see the whole subject:
A formula can give a correct answer, while the conclusion is still wrong.
How is this possible? Maybe the data was collected badly. Maybe the sample was biased, like my coffee example. Maybe we measured the wrong thing. Maybe two things move together, but one does not cause the other. Or maybe we simply read the result in the wrong way.
So now I see statistics less as a set of formulas, and more as a way of thinking. Before any calculation, I try to ask:
- What am I trying to understand?
- Where did the data come from?
- Who is included, and who is missing?
- What does this number really mean?
- How sure should I be?
For me, these questions are the heart of statistics.
What we have learned today
- The population is the whole group we want to understand. The sample is the smaller group we actually study.
- Descriptive statistics describes the data we already have.
- Inferential statistics uses a sample to make conclusions about the whole population, with some uncertainty.
- A biased sample can give wrong answers, and a bigger sample does not fix bias.
- Qualitative data = categories. Quantitative data = numbers that measure how much or how many.
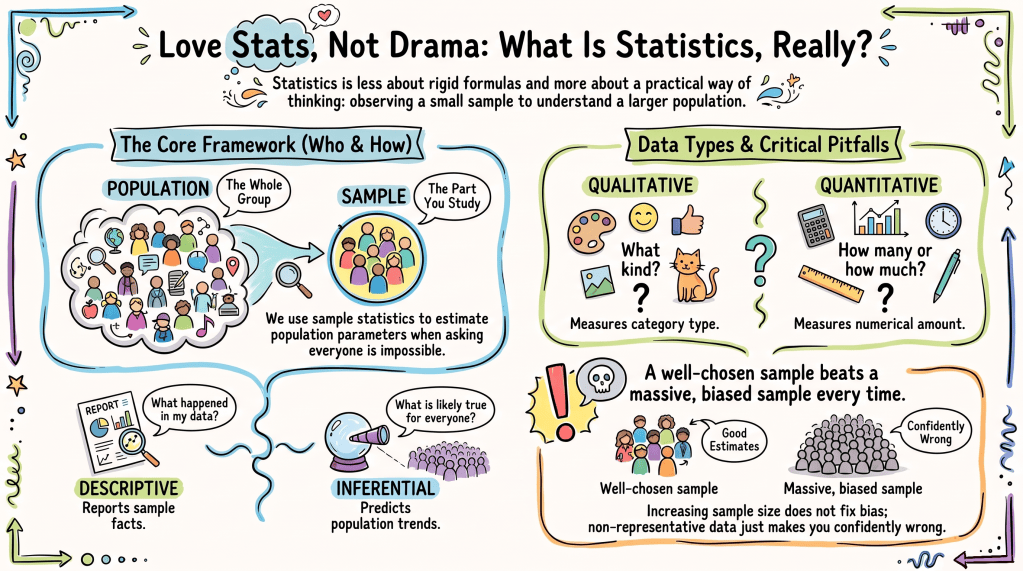
Figure 1 Summary of what we have learned today
A small challenge before next time
Is a postal code qualitative or quantitative?
It is written with numbers… but does it tell you “how much”? Could you calculate an “average postal code”, and would it mean anything?
Write your answer in the comments. I’d love to see how you think about it!
One final thought
Statistics becomes much less scary once we stop seeing it as a wall of equations. At its heart, it is something very human:
We observe a little, and we try to understand a lot.
The hard part is doing this carefully. That is what I want to explore in this series: slowly, practically, and with lots of everyday examples.
In the next diary entry, we will look at something we all know: mean, median, and mode. They look easy, but choosing the wrong “average” can tell a very different story.
See you in the next diary entry!


Leave a Reply